GLAM extraction benchmark
National Library of Scotland manuscript index cards
98 documents · 10 models · National Library of Scotland
Images and checked labels: NationalLibraryOfScotland/index-cards-eval (cc0-1.0). Labels drafted by Qwen3.6-35B-A3B-GGUF-Q8_0 and reviewed by NLS cataloguers.
Predictions were generated for this benchmark config and revision.
Risk is a wrong identifier or an invented field. Workload is a blank field that someone must fill. F1 combines extraction precision and recall. This is a small evaluation set; neighbouring scores should not be read as a definitive ranking.
Uses total parameters, including for mixture-of-experts models. Unknown sizes appear under All. Click a column heading to sort; click again to reverse.
| Qwen3.8-27B 27.78B | 12.7% | 1.4% | 19.2% | 79.5 |
| GLM-5.3-Flash 321.32B | 19.9% | 4.1% | 13.0% | 83.1 |
| Qwen3.5-9B 9.65B | 27.2% | 8.4% | 26.7% | 70.5 |
| Qwen3-VL-8B 8.767B | 27.2% | 15.0% | 22.2% | 74.9 |
| NuExtract-3 4.539B | 28.3% | 12.9% | 14.5% | 73.5 |
| Qwen3-VL-235B 235.67B | 29.0% | 23.4% | 10.6% | 77.8 |
| gemma-4-E4B 7.996B | 34.2% | 11.9% | 43.6% | 57.7 |
| Qwen3.5-4B 4.660B | 37.4% | 5.7% | 24.9% | 71.7 |
| Qwen3.5-2B 2.274B | 48.3% | 7.3% | 47.8% | 45.0 |
| Granite-Vision-4.1-4B 3.997B | 86.1% | 19.2% | 32.1% | 62.6 |
No models match this size limit.
Rates are micro-averaged over documents; F1 is the mean per-document score. An em dash means no gold identifiers were filled, not zero errors. Excluded fields: notes.
Size vs. extraction quality
Upper-left is better: smaller models, higher F1. Teal points and the dashed line show the observed Pareto frontier: no other model uses as few parameters and scores as highly. Small score differences may be noise.
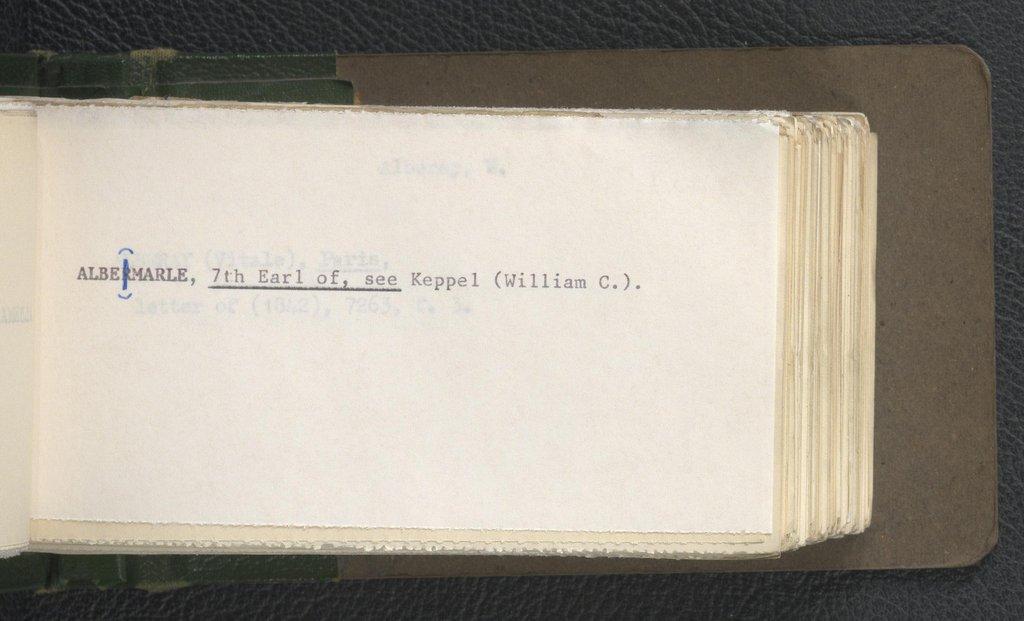
Inspect an example document and its checked output
Reproducibility and downloads
Config: nls-index-cards;
split: test; dataset revision ecc9c02582f9.
Harness 0.0.1; scorer 2026-08-26a. Raw prediction files retain their original inference provenance.
Scores and run provenance · Dataset manifest · Code · Raw predictions